15. Basic SEO paging skills
· Members only
Preview
1. Implementation of pager
Bad Case
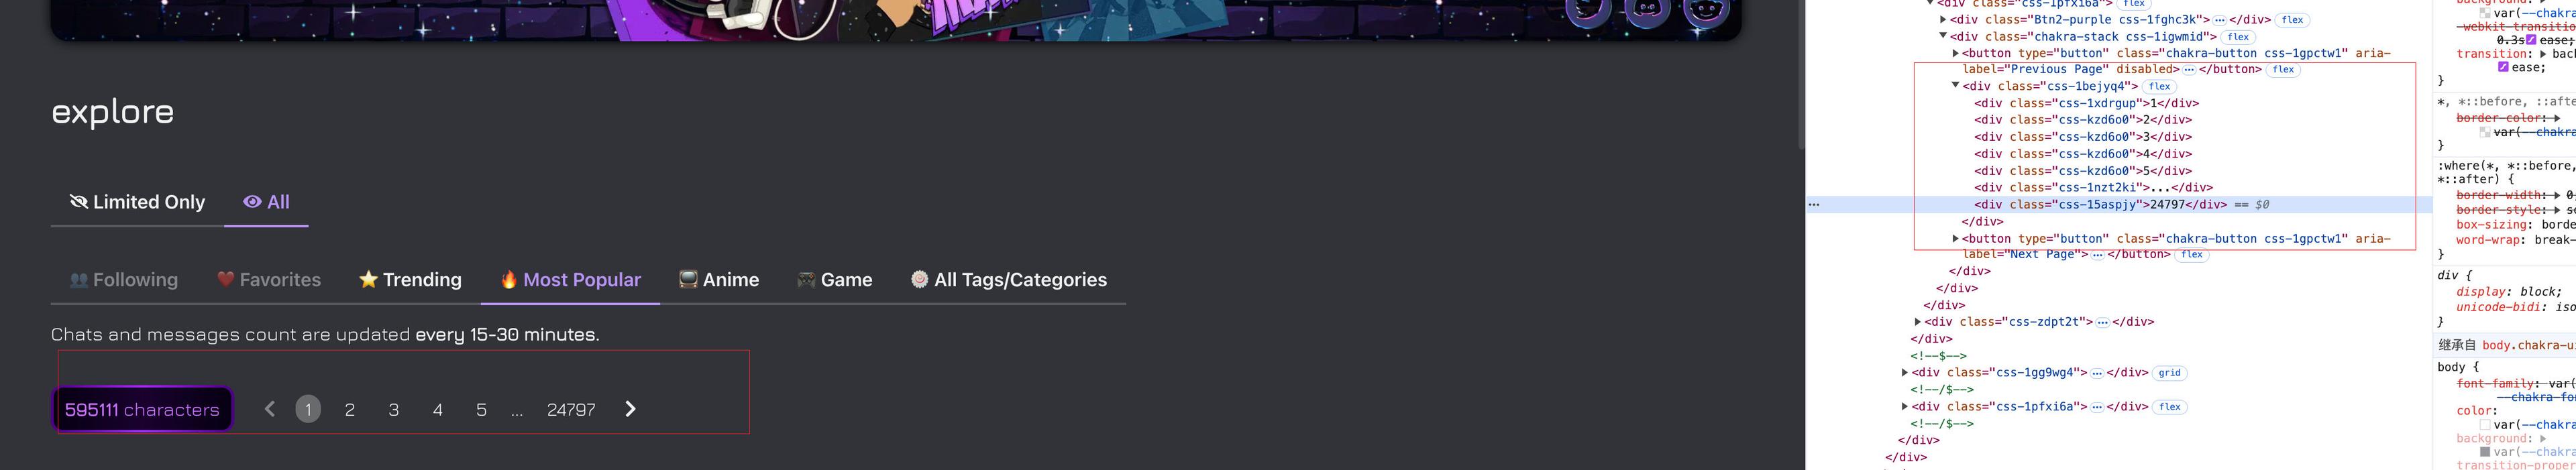
As shown in the picture, this is a pager implemented by Janitorai, which is in the form of div.
We go to SEMRush to query the traffic of this page. We can observe that only the data of the first page has been crawled for this entire page.
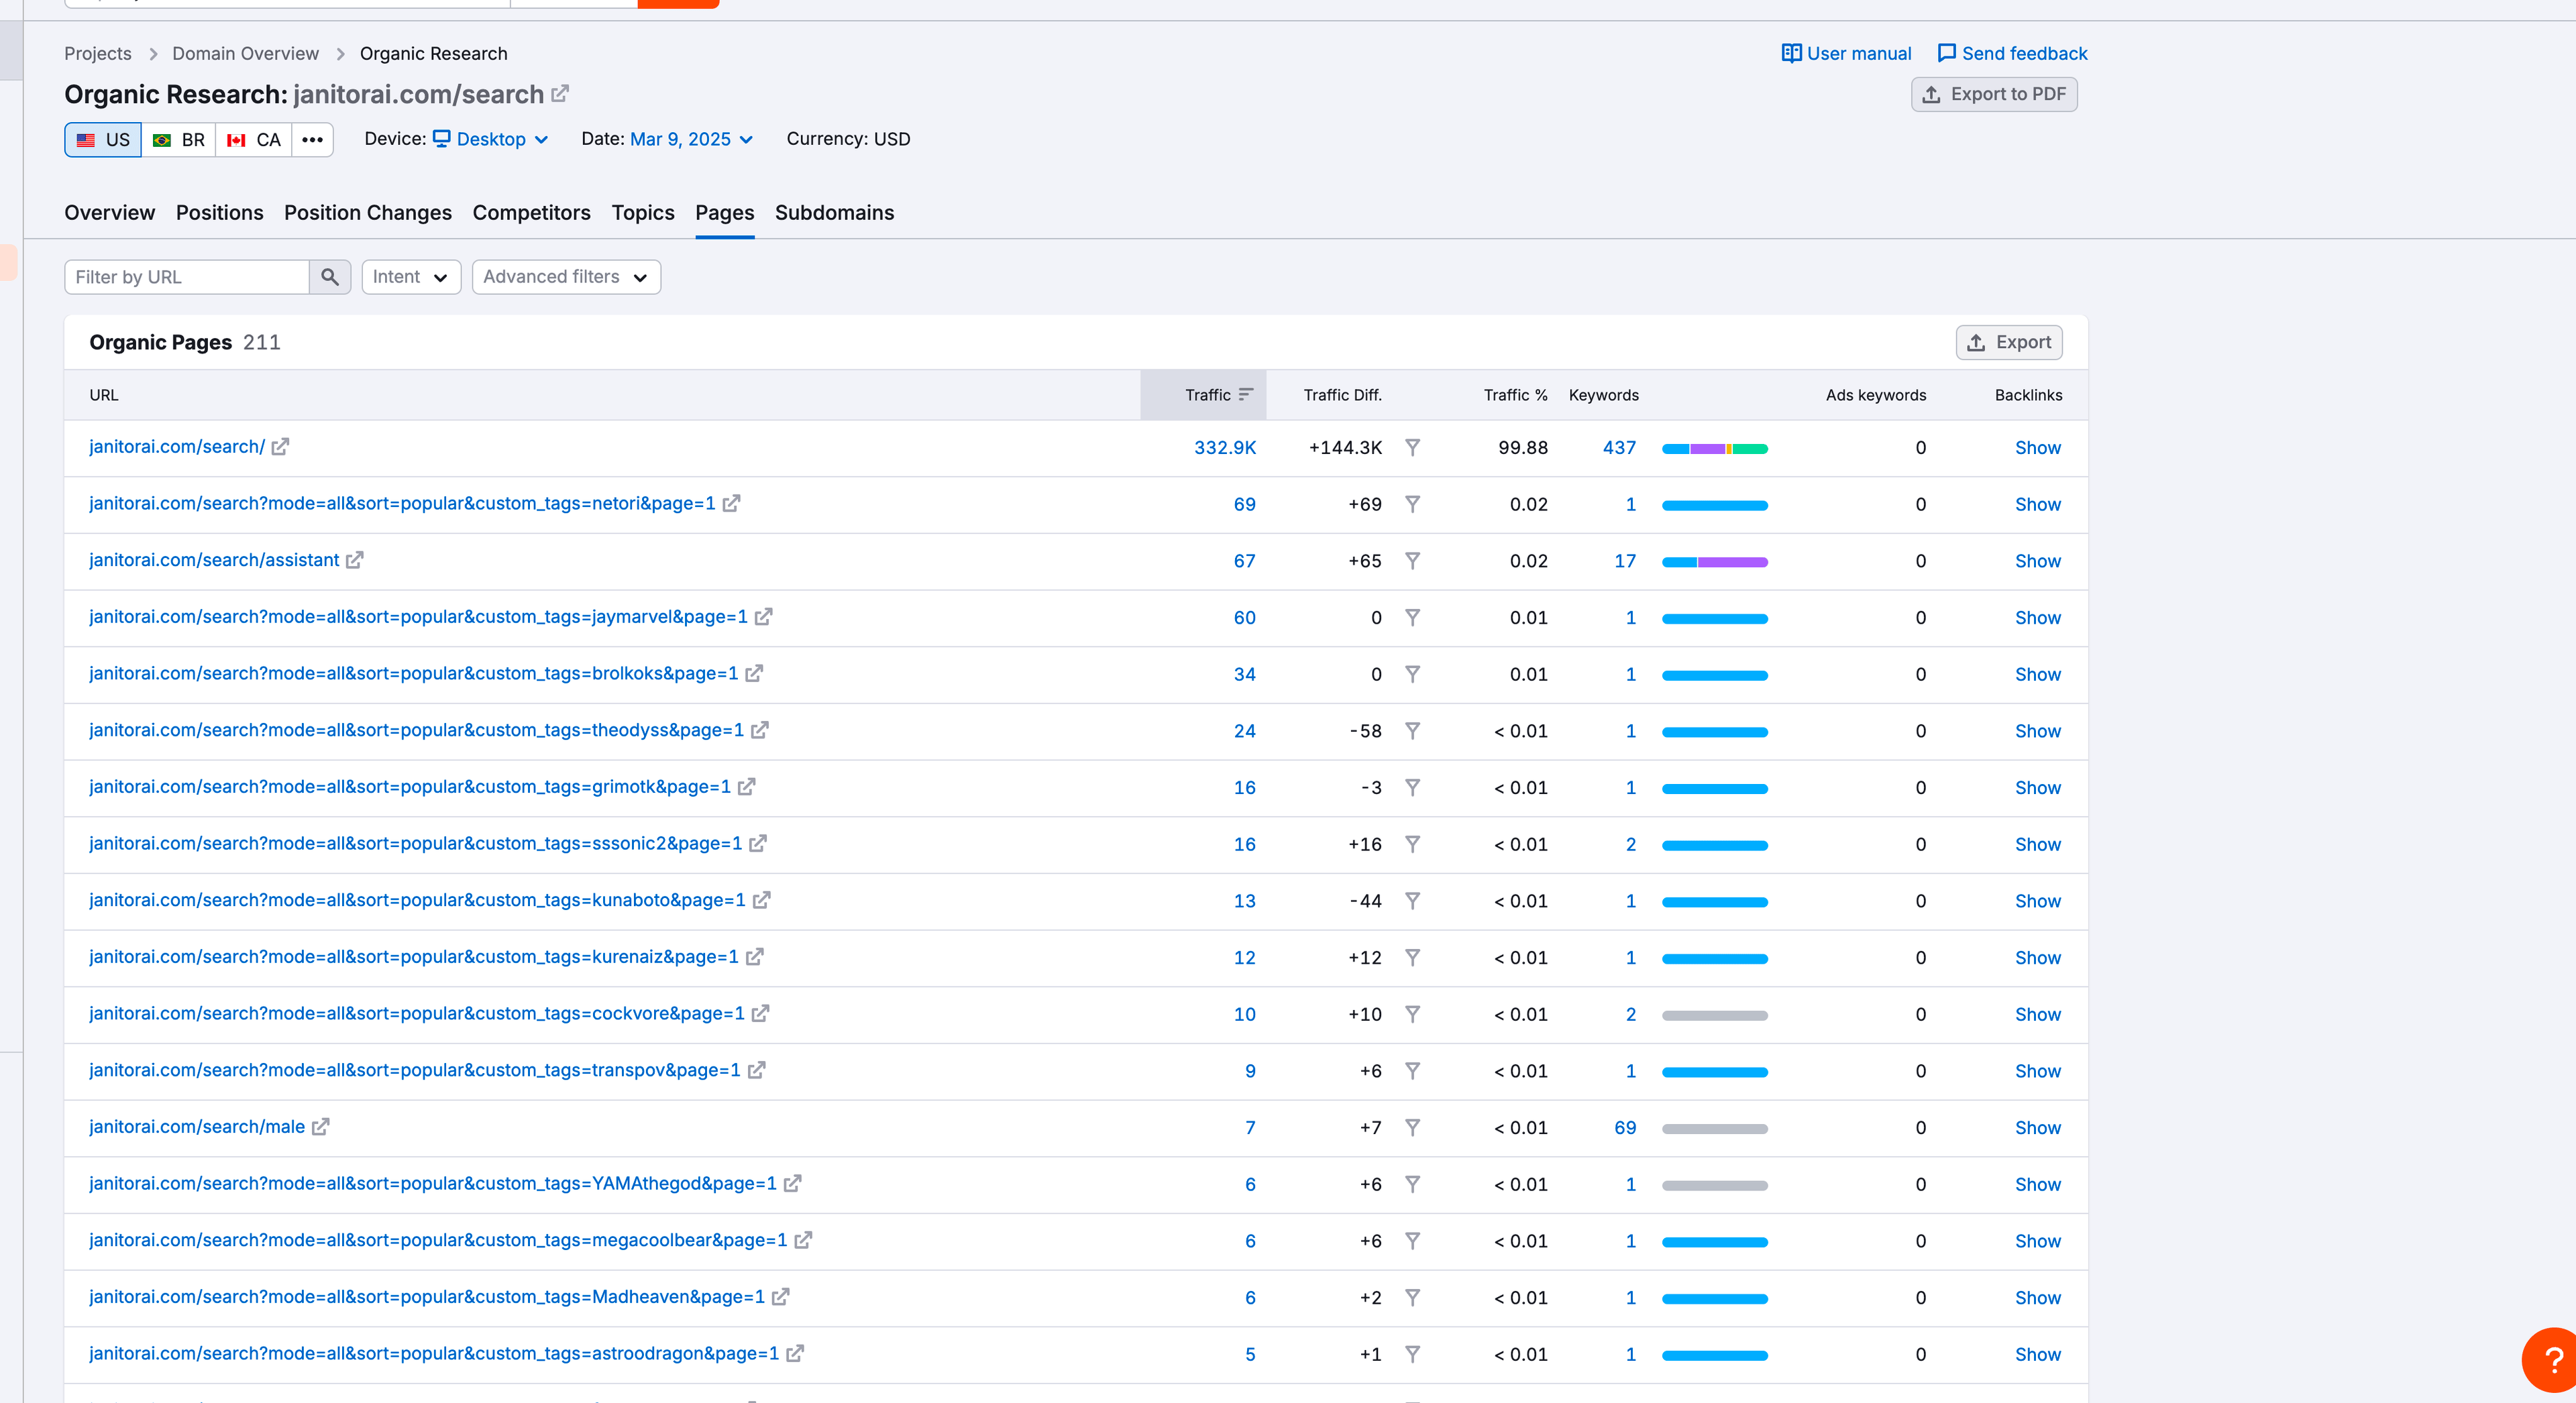
This actually verifies the working principle of Chapter 7, 1.3 Googlebot: Googlebot will first analyze the link to be crawled (a tag) in the HTML and the JS file that needs to be downloaded, selectively download the JS file, and then try to render and execute the JS. However, this step itself consumes a lot of resources or has problems such as JS execution errors. There is a high probability that it will fail or will not be executed at all.
Comments
No comments yet. Be the first to add one.